← Back to Portfolio
Project 06 · Audio Forensics & Security

VoiceGuard

Continuous acoustic verification and deepfake synthesis detection for live calls, streams, and virtual conferences — using a fine-tuned self-supervised speech encoder, entirely on-device.

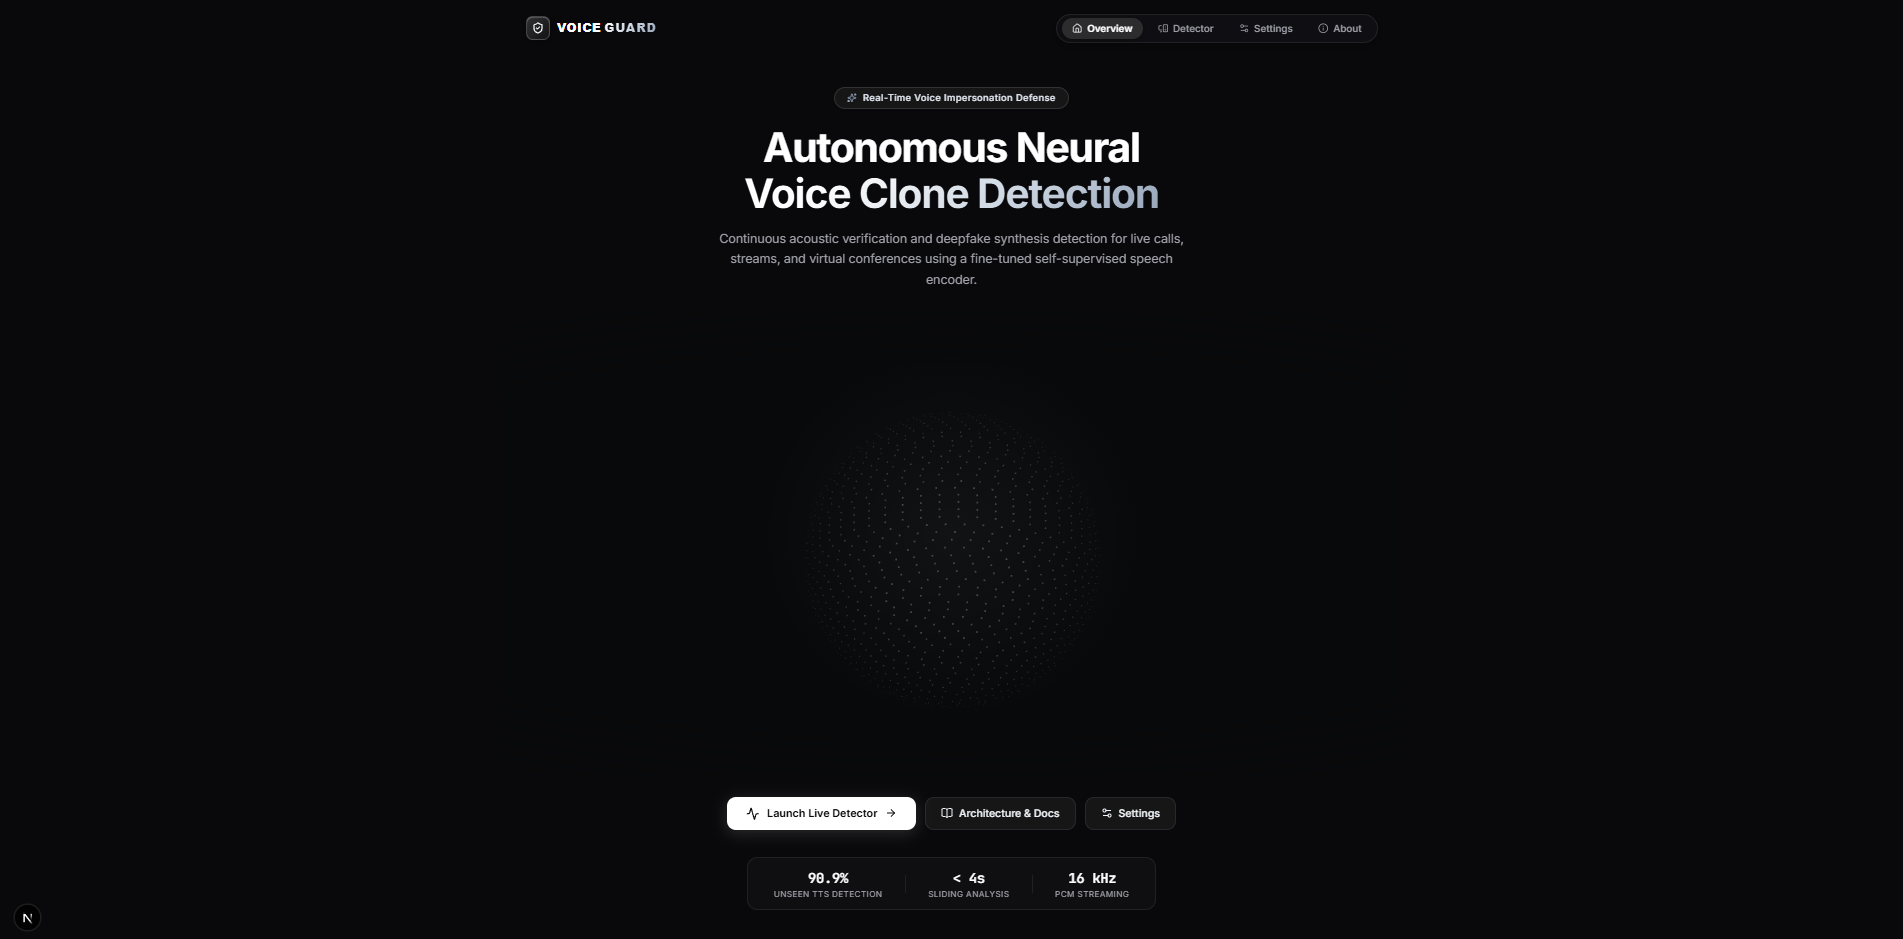
VoiceGuard overview — Autonomous Neural Voice Clone Detection
Overview

VoiceGuard detects deepfake and synthetic voice attacks in real time, across both live voice streams and recorded audio files. It defends voice channels against impersonation and against synthetic voice generators such as ElevenLabs, ChatTTS and Edge-TTS.

Rather than returning an opaque verdict, it produces a transparent 0–100 Live Risk Score built from three independent forensic signals — so a reviewer can see why a sample was flagged, not just that it was.

At a Glance
~13 ms
Inference per 4s window
On GPU
<200 ms
Inference per 4s window
On CPU
98.9%
Unseen TTS detection
Held-out generators
16 kHz
Live PCM stream, mono
Sliding 4s analysis
100%
Local, on-device inference
No persistent storage
Tri-Signal Architecture

Three independent forensic signals are computed in parallel, then fused into one explainable score.

Raw Audio Stream / File ↓ Preprocessing (16 kHz mono) ↓ ┌────────────────┼────────────────┐ ↓ ↓ ↓ wav2vec2 ECAPA-TDNN Praat / Parselmouth (fine-tuned) (SpeechBrain) Prosody forensics Synthetic Speaker Naturalness speech detect verification F0 · jitter · shimmer · HNR │ │ │ Bonafide (0-1) Cosine sim (0-1) Naturalness (0-1) └────────────────┼────────────────┘ ↓ Explainable Fusion Scorer ↓ Risk Score (0-100) ↓ Live Risk Dashboard & Alerts
Fusion Engine

The three signals combine through transparent, configurable weights. No hidden ensemble — the contribution of each signal is inspectable and tunable at runtime via the config endpoint.

Risk = ( w_spoof · (1 − S_bonafide) + w_speaker · (1 − S_speaker) + w_prosody · (1 − S_naturalness) ) × 100
Key Features
API Surface
Analysis
POST /analyze WS /ws/analyze
Identity
POST /enroll
Configuration
/config
Tech Stack
Backend
Python 3.10+ PyTorch FastAPI WebSockets
Audio & Models
wav2vec2 AASIST-L ECAPA-TDNN SpeechBrain Librosa Praat / Parselmouth
Frontend
Next.js 16 React TypeScript Tailwind CSS Lucide Icons
Interface